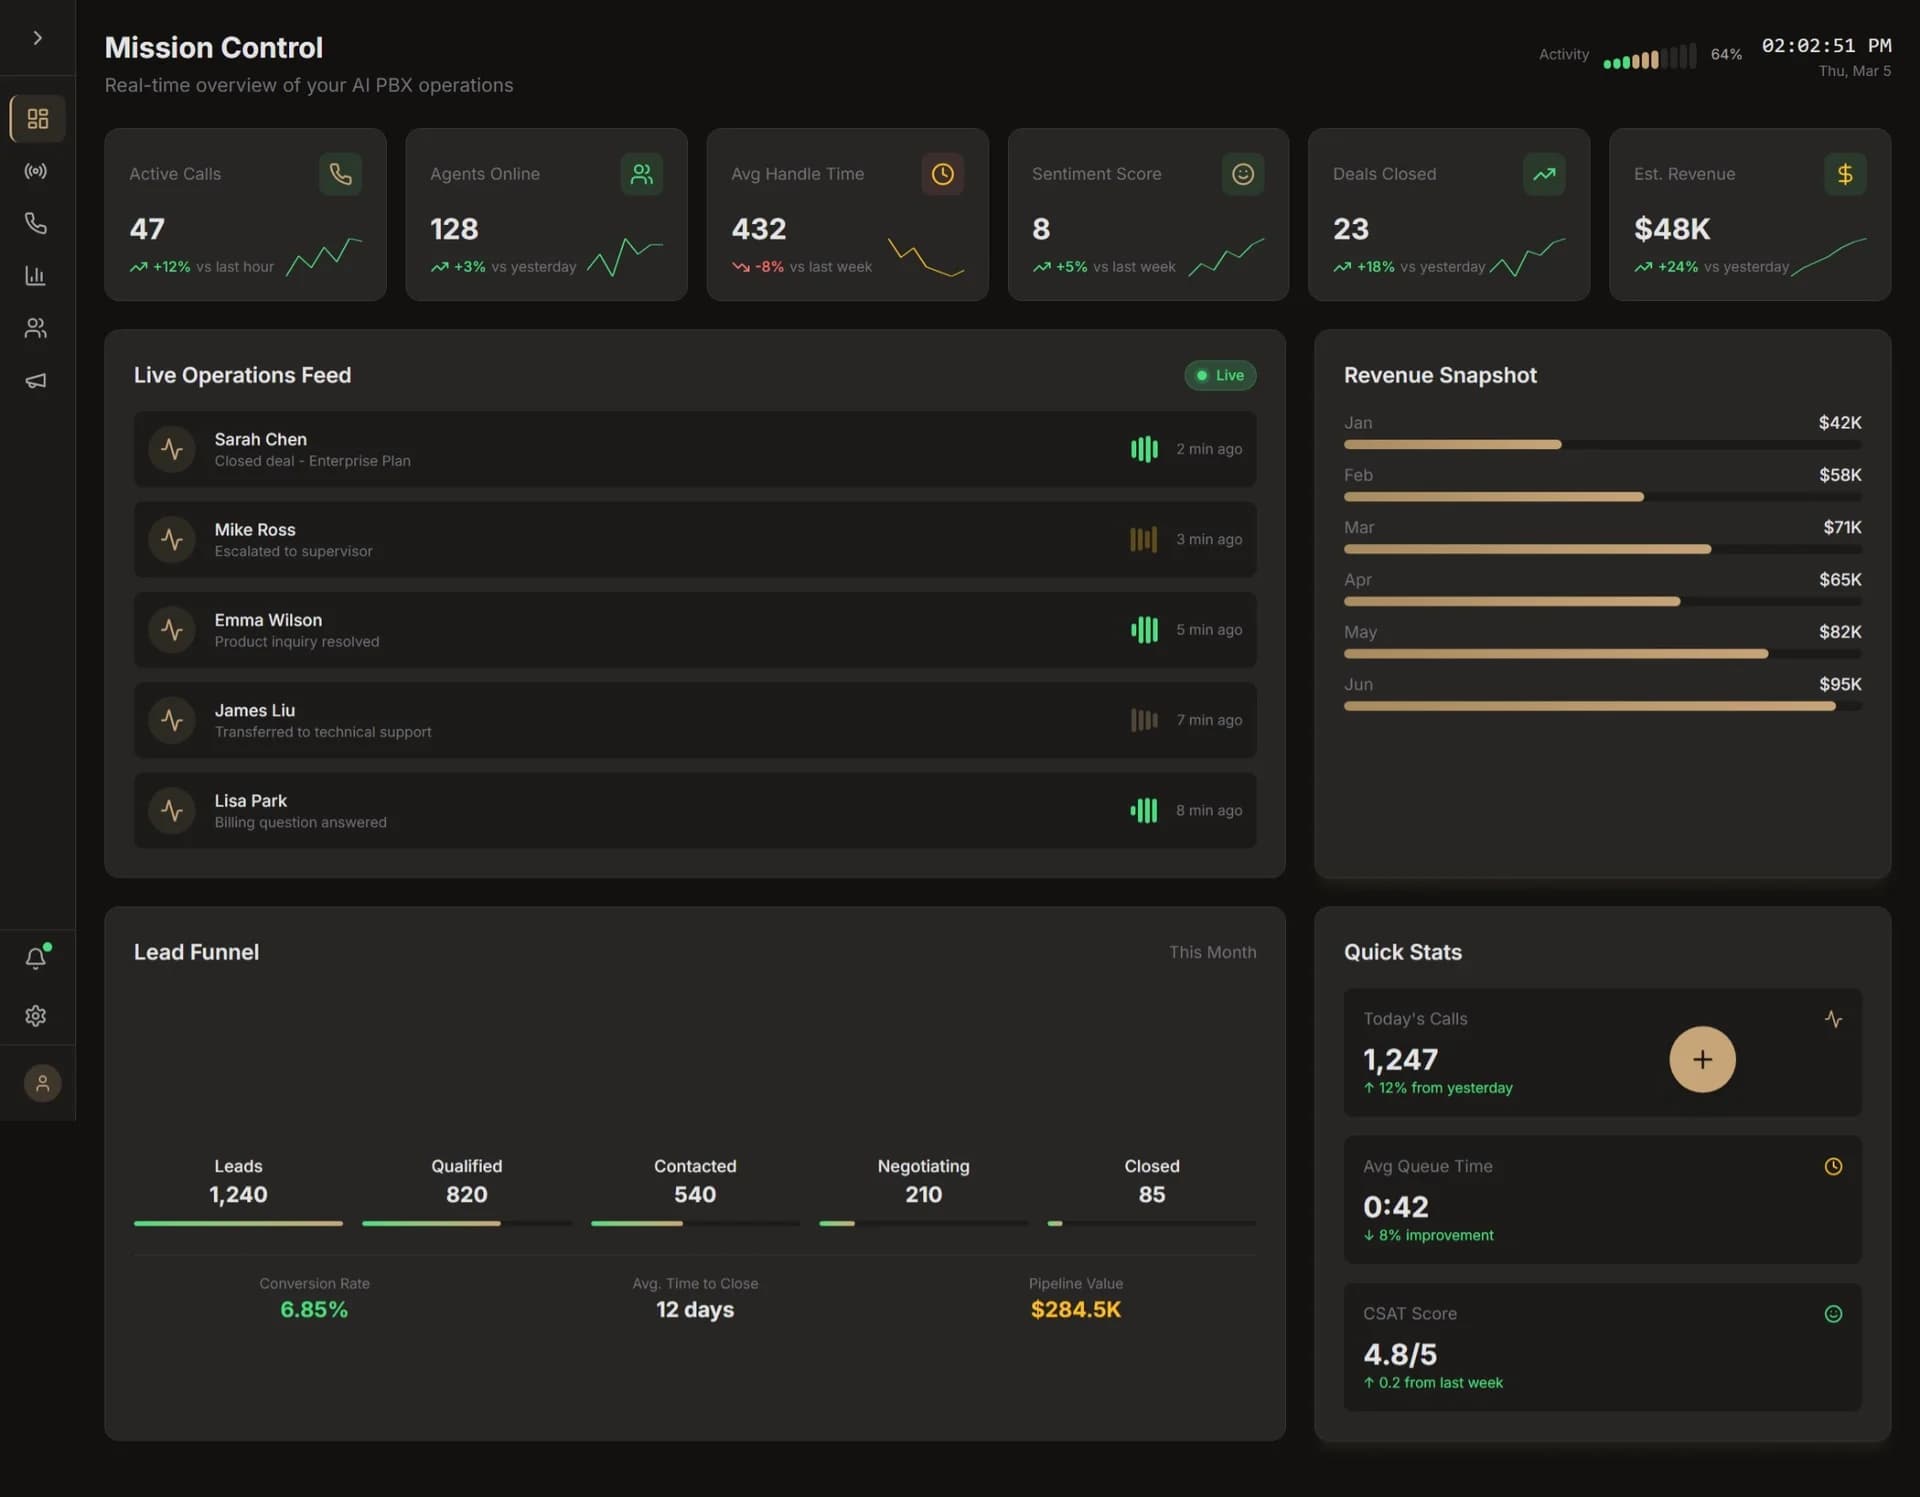
Speak NaturallyThink LocallyRespond Instantly
We built a fully local multi-agent PBX system with sub-200ms latency — no cloud dependency, no audio leaving the building.

The case in one scan.
A fast read on the operational context, engineering scope, and measured business value before the deeper story begins.
Context-specific workflows
Ultra-Low-Latency STT + Multi-Agent Orchestration + Fully Local Processing
5 controlled phases
Chosen for the operating constraint
Performance metrics 60 days post-deployment across 50,000+ handled calls
Calculated from 68% reduction in live agent handling time and eliminated cloud API fees
Cloud Voice Agents Couldn't Meet Privacy or Speed Requirements
Enterprise clients handling sensitive financial and healthcare conversations couldn't use cloud-based voice AI due to strict data residency requirements and regulatory compliance mandates including HIPAA and PCI-DSS. Existing solutions like Twilio and cloud STT/TTS services introduced 800-1200ms latency, creating unnatural conversation pauses that callers immediately noticed and found frustrating. The client's existing IVR system suffered from a 67% caller abandonment rate during peak hours, with customers citing endless menu trees and robotic voices as primary complaints. Internal support teams were overwhelmed with routine inquiries that AI could handle, but the latency and privacy constraints made existing voice AI platforms non-starters for this highly regulated industry.

Where the operation was leaking value
The problem was not one broken screen. It was a chain of small operational delays compounding across every shift.

Local-First
Voice Intelligence
We architected a fully on-premise multi-agent voice platform that processes every audio stream locally, ensuring sensitive conversations never leave the client's infrastructure. LiveKit handles real-time WebRTC transport with sub-50ms audio delivery, while Moonshine STT provides on-device speech recognition that outperforms cloud alternatives for domain-specific terminology. A modular TTS layer combines Pocket TTS for natural-sounding responses with cloud fallback voices for edge cases, all orchestrated by a custom AI layer that maintains conversation context across turns and routes complex intents to the appropriate specialized agent. FastAPI and Go microservices manage the orchestration layer with Redis Streams providing durable message queues for handoff events, enabling seamless transfers to live human agents when escalation is needed.
From disconnected work
to one live system.
Fewer handoffs, faster decisions, and one source of truth connecting the teams, devices, and workflows that used to drift apart.
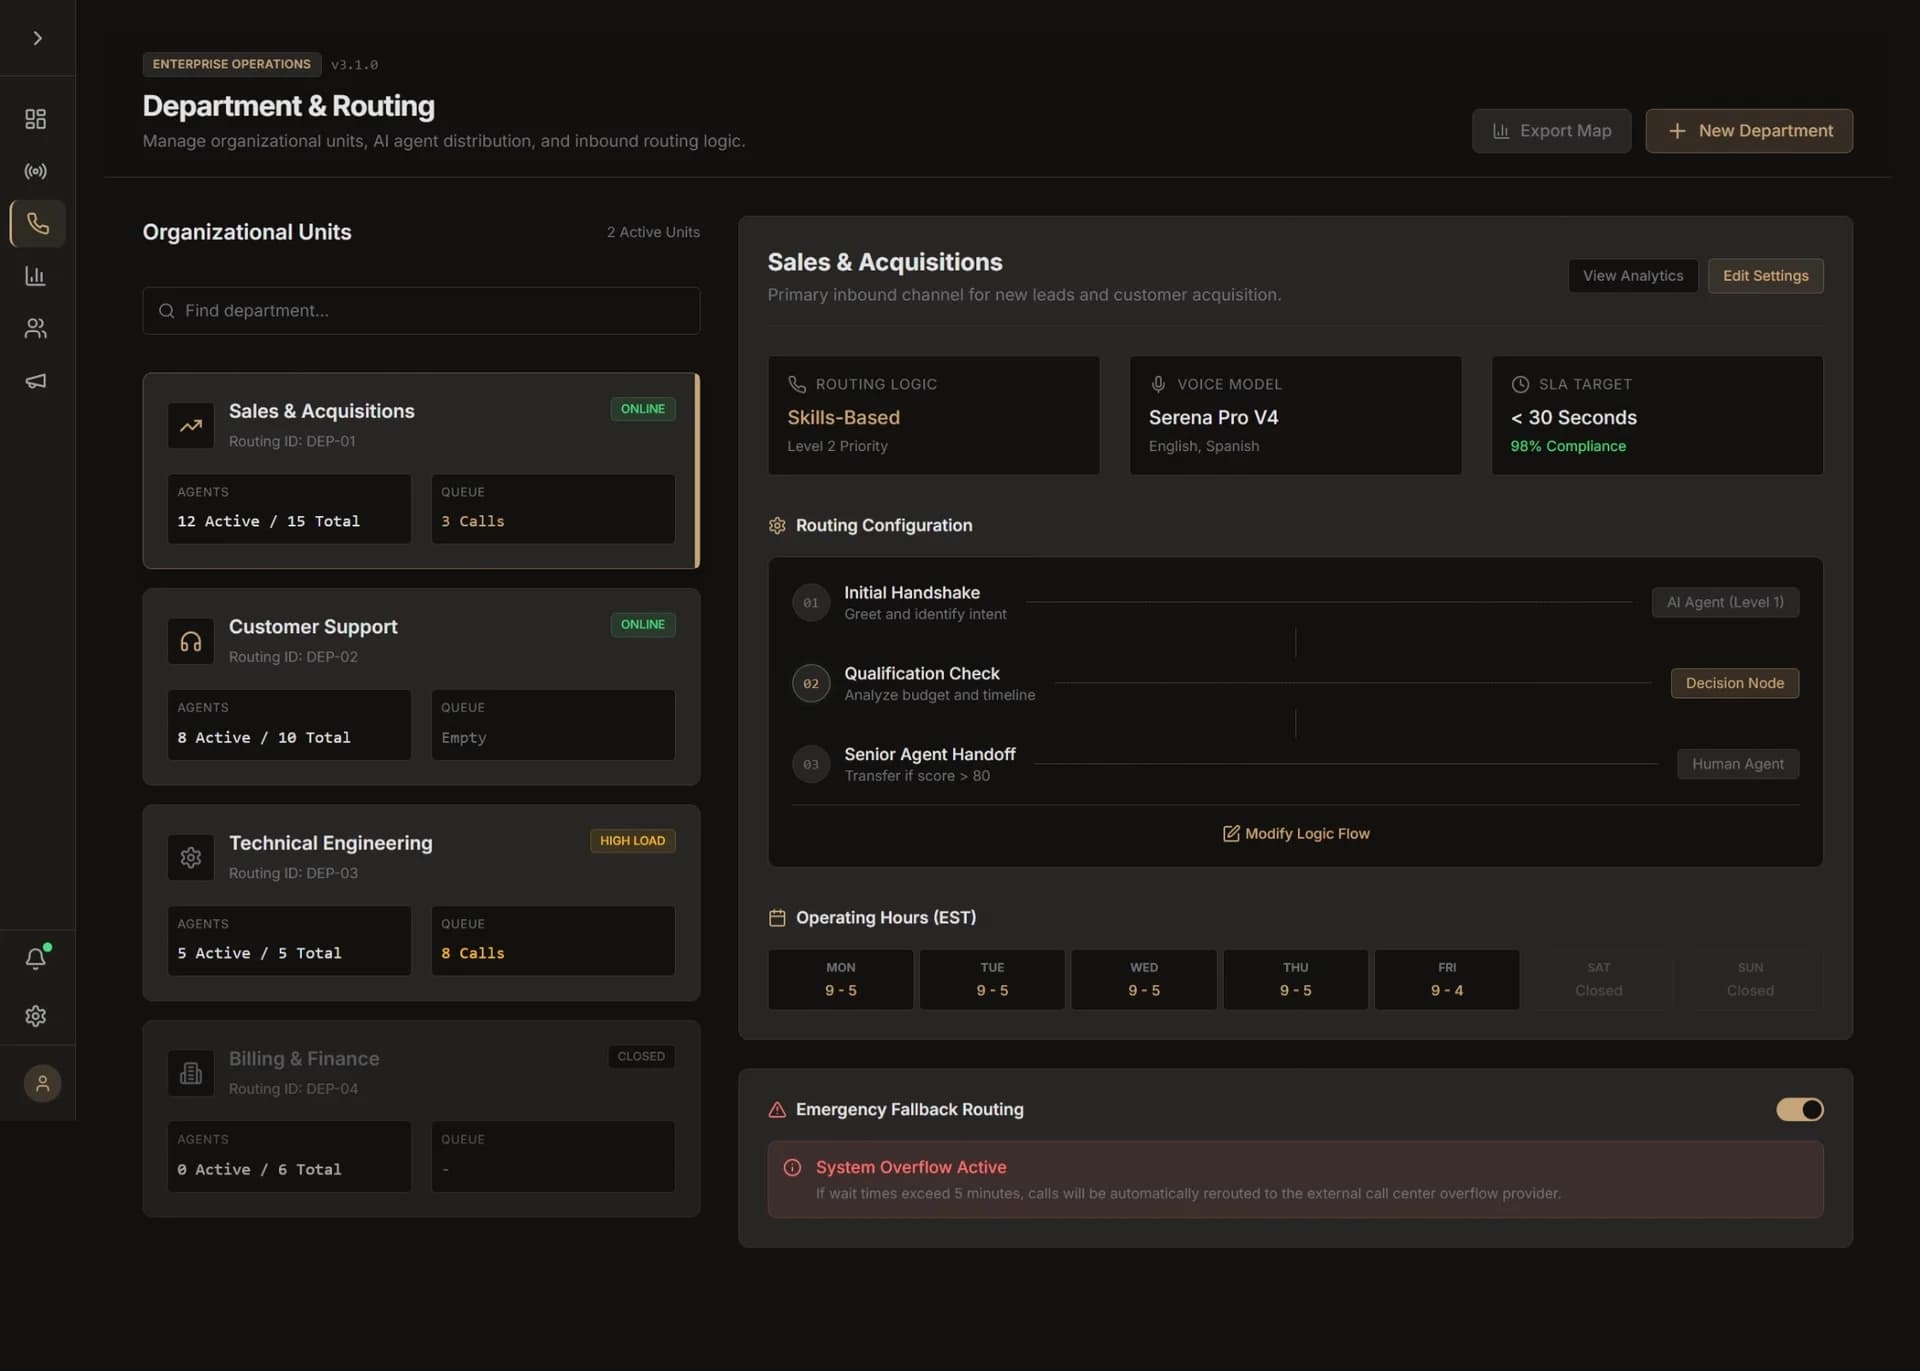
Architecture Built
For the Outcome.
Each technical decision maps to a business constraint: speed, resilience, scale, privacy, or long-term maintainability.
 Transport
 Orchestration
 Concurrency


 Cloud
“We chose Moonshine STT over cloud-based alternatives because on-device inference eliminates network roundtrips entirely — critical when 200ms is the difference between natural conversation and awkward silence.”
— Lead Architect, KreativeTek Solutions
TransportOrchestrationConcurrencyCloud“We chose Moonshine STT over cloud-based alternatives because on-device inference eliminates network roundtrips entirely — critical when 200ms is the difference between natural conversation and awkward silence.”
— Lead Architect, KreativeTek Solutions
From Cloud Dependency to Local Intelligence
Delivered in 12 weeks from architecture to production deployment
Requirements & Compliance Mapping
Weeks 1-2Architecture & Technology Selection
Weeks 3-4Core Platform Development
Weeks 5-9Integration & Compliance Testing
Weeks 10-11Production Rollout
Week 12
Measurable Voice Intelligence
Performance metrics 60 days post-deployment across 50,000+ handled calls


Before vs. After
The transformation eliminated cloud dependency while dramatically improving caller experience — a regulatory-compliant voice AI that actually sounds human.
Voice Response Latency
Caller Abandonment Rate
Calls Requiring Live Agent
Average Call Duration
Data Residency Compliance
Verified production metrics from the live engagement. Details withheld where required by NDA.

Ready for Local Voice Intelligence?
Let's architect a privacy-first voice platform tailored to your compliance requirements.